
An email lands in an employee’s inbox. Nobody opens it. Nobody clicks anything.
Later, the employee asks Microsoft 365 Copilot a routine business question, something like “summarize our earnings report.” Copilot retrieves relevant material to answer, and the planted email, which carries hidden instructions, gets pulled in with it. Copilot then leaks sensitive data to the attacker, with no click from the user.
That’s EchoLeak. Aim Security found it, it carries the identifier CVE-2025-32711, and it scored 9.3 out of 10 on severity. Microsoft fixed it on its side in June 2025, customers didn’t need to do anything, and there’s no evidence anyone exploited it in the wild.
Read that again, though. The attacker never touched the victim’s machine. They sent text.
And here’s the thing. Microsoft’s own advisory labeled it AI command injection in Copilot. If you’ve built a web app, that wording should ring a bell. It’s the SQL injection shape, back again.
Most explanations stop right there: it’s the new SQL injection, so validate your inputs. That’s half right. The half that’s wrong is the half that costs money.
What the 2 attacks really share
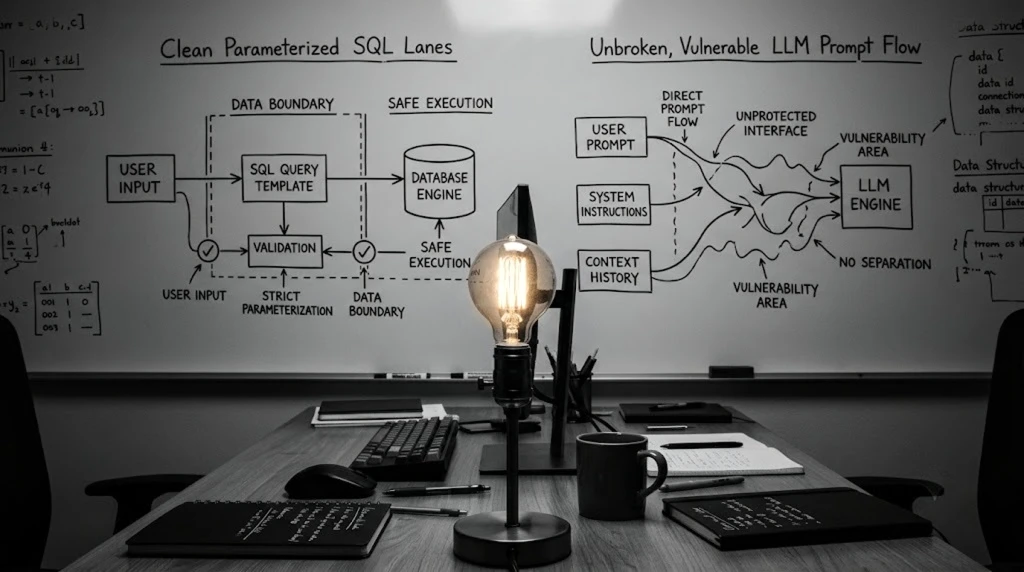
Both bugs have the same anatomy. An application builds one blob of text from two ingredients, instructions it trusts and input it doesn’t, then hands the blob to something that executes it. For SQL, that something is a database. For an LLM feature, it’s the model.
SQL injection is old. The first documented exploit dates to 1998. Here’s what it looks like when a company gets it wrong. Between October 15 and 21, 2015, an attacker used SQL injection to pull personal data on 156,959 TalkTalk customers. The UK’s ICO fined the company £400,000, about $511,000 at the time, and noted that user input had not been validated. Two earlier SQL injection attacks that year had never prompted a fix. The company reportedly lost over 100,000 customers and tens of millions of pounds.
Hmm. A bug class everyone understood, with a fix everyone knew about. Keep that in your head, because the next section is about a bug class where the second half isn’t true.
Where the comparison breaks- the fix
SQL injection got boring once parameterized queries became standard. With parameterization, the database engine can’t interpret the input as an instruction, whatever the input says. The command and the data travel in separate lanes.
A language model has no second lane. The UK’s National Cyber Security Centre said in a December 2025 blog that, because an LLM has no inherent distinction between data and instruction, prompt injection may never be totally mitigated the way SQL injection can be.
Wait — it gets more interesting. The NCSC itself said roughly two years earlier that prompt injection might become the SQL injection of the future. The agency that made the analogy has now warned against leaning on it, because the comparison hides the one thing that matters: SQL injection has a proper mitigation, and prompt injection probably won’t get one of the same kind.
OWASP lands in the same place. Steve Wilson, co-chair of the OWASP GenAI Security Project, said prompt injection is fundamentally different from SQL injection because no known engineering fix definitively eliminates it, and OWASP advises managing it as an ongoing operational risk. It topped OWASP’s LLM Top 10 for the third year running in the edition published in early August 2026.
Why “just validate the input” stops working
Validation works for SQL because SQL is a formal language. You know which structures are dangerous, and parameterization removes the need to guess at all. Natural language has no perimeter like that. An instruction can be phrased a thousand ways, in any language, buried in a long document. The 2026 OWASP list now counts instructions hidden in images or audio as prompt injection too.
So when someone says the team added a filter, understand what that is: a guess about what attacks look like. Hold that thought, because the numbers in the next section are about exactly that.
If you’ve shipped an LLM feature and want a second set of eyes before a customer’s security team asks about it, that’s what our AI red teaming work is for: www.snippipedia.com/contact
Is this actually happening, or just a conference problem?
Fair question, and the honest answer is both.
CrowdStrike’s 2026 Global Threat Report found that in 2025 attackers exploited legitimate generative AI tools at more than 90 organizations by injecting malicious prompts, generating commands that stole credentials and cryptocurrency.
Now the part that doesn’t fit a scary headline. OWASP’s own analysis says that ranked by recorded incidents alone, prompt injection wouldn’t even make the top 10. OWASP attributes the gap to a defense effect: teams fight it so hard that fewer clean exploits reach public databases.
I read that as under-reported, not overrated. And yes, I sell this kind of testing, so weigh my read accordingly. But the data isn’t one-sided, and anyone who shows you only the scary half is leaving something out.
The defense numbers are harder to explain away. In January 2025, NIST’s Center for AI Standards and Innovation tested AI agents in simulated tasks. The strongest standard attack succeeded 11% of the time. Attacks its red teamers tailored to the target succeeded 81% of the time. A later NIST-backed public competition logged more than 250,000 attack attempts from over 400 participants and found at least one successful attack against every frontier model it tested.
And honestly, this next one should end the “we added a filter” conversation. Researchers from OpenAI, Anthropic, and Google DeepMind took 12 published jailbreak and prompt injection defenses and hit them with adaptive attacks. Most fell at success rates above 90%, and most of those defenses had originally reported near-zero. Each defense was tested on its own benchmark, so treat the exact percentages as directional. The takeaway, as Simon Willison summarized it, is that a fixed list of example attacks tells you almost nothing about a defense.
That applies to your own testing too. A defense that scores zero against a published payload list has told you very little.
What to do when there’s no patch
You can’t close the hole, so you shrink what’s behind it. 6 moves, in the order I’d do them:
1- Decide whether the use case can live with leftover risk. The NCSC’s advice is blunt: if an application can’t tolerate the residual risk, an LLM may not be the right tool for it.
2- Count your trifecta. Simon Willison named the lethal trifecta in June 2025: private data, untrusted content, and a way to send data out. Meta’s Agents Rule of Two, published in late 2025, turns that into a budget: within one session, an agent should have no more than two of three properties. Those are processing untrusted input, accessing sensitive systems or private data, and changing state or communicating externally.
3- Shrink tool permissions. OWASP’s advised mitigations include limiting which tools an agent can use, what each tool can do, and which permissions each tool holds.
4- Treat model output as untrusted input. This is the SQL injection lesson that does transfer. Anything the model produces that reaches a database, a shell, or an API gets validated on the way out. Authorization comes from the signed-in session, never from what the model says it’s allowed to do.
5- Put a human in front of anything you can’t undo. Sending money, emailing customers, deleting records.
6- Test like an attacker who gets to iterate, and log what the model read and which tools it called. One scan with a payload list isn’t a test. If you already commission web application penetration testing, check whether the scope covers your LLM features. A scope written before you added the chatbot probably doesn’t. AI penetration testing and AI red teaming exist to fill that gap.
The one thing to take away
Prompt injection looks like SQL injection until you reach for the fix, and then the resemblance ends.
Waiting costs more than acting here. Anything you ship this quarter with tool access will get probed, and the cheapest time to limit what a hijacked model can do is the design meeting, not the incident call.
If you want that design review done by someone who tests this for a living, send a short description of what your model can read and what it can do through www.snippipedia.com/contact. We’ll scope an AI red team review around it.